RETRIEVAL
Document research chatbot
I built a document research assistant that lets users ask questions about uploaded files and trace answers back to the source.
- PDF, TXT, CSV + images
- 900-character chunks · 150-character overlap
From a file to a traceable answer
The project explores a practical research task: finding a specific fact inside an uploaded document without losing the context it came from. The interface connects a conversational question with retrieved passages, so a reader can compare the response against the original material.
Files are parsed into overlapping text chunks before being embedded and indexed. Retrieval selects relevant chunks for the language model, while document and chunk references give the user a path back to the evidence. Image support adds a separate route through OCR and a local vision model.
My contribution
I implemented the full application for an INFO 533 team project: a Streamlit chat interface, document parsing and chunking, Sentence Transformers embeddings, FAISS indexing, and retrieval with LangChain and Ollama. I also added image processing with a local vision model and Tesseract OCR.
The output
Answers with retrieved document, page, and chunk references. The application uses local Llama models and prompts designed to ground responses in uploaded content.
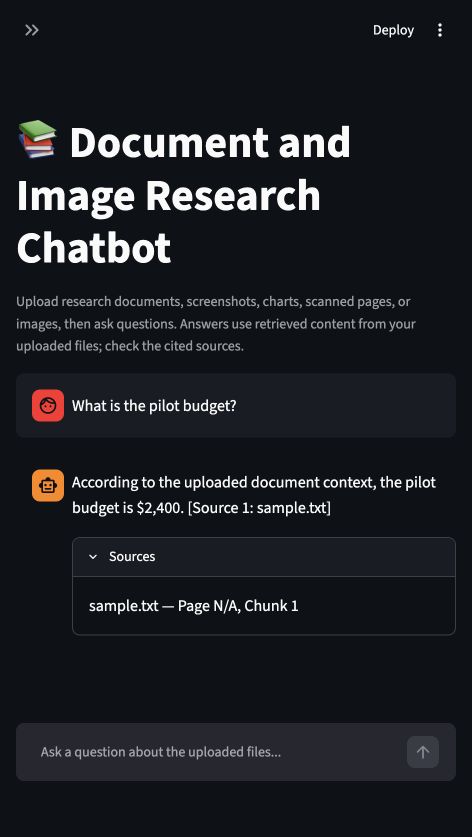
A sourced answer, step by step
Open each step to follow the same fact through the workflow. Start with the short research note, compare the budget question with the saved answer, and then inspect the source reference. The example demonstrates traceability using synthetic information; it does not evaluate the system across a larger test set.